
1. Introduction: why AI alone isn't always enough
AI can write with astonishing fluency.
It can explain a complex concept, summarize a report, draft a customer message or help you think through a strategy. But by now, many people are also familiar with its biggest weakness: it can answer confidently even when it doesn't have enough information. It can sound like an expert while it is guessing.
This is an especially big problem at work. Companies usually don't want just polished text from AI. They want answers grounded in the right documents, up-to-date information, internal guidelines, customer data or reliable sources.
This need gave rise to RAG, or Retrieval-Augmented Generation.
The name is a mouthful, but the idea is simple: AI doesn't answer from its memory or training data alone. It first retrieves information from a defined source and then builds its answer on that.
Google Cloud describes RAG as an AI framework that combines traditional information retrieval, such as search systems and databases, with the ability of generative language models to produce natural language. The goal is to make answers more accurate, more up to date and better suited to the user's specific needs.[1]
Put more simply: RAG gives AI a library card. Instead of trying to answer from memory alone, the model gets the chance to check the relevant information before it responds.
2. What does RAG mean?
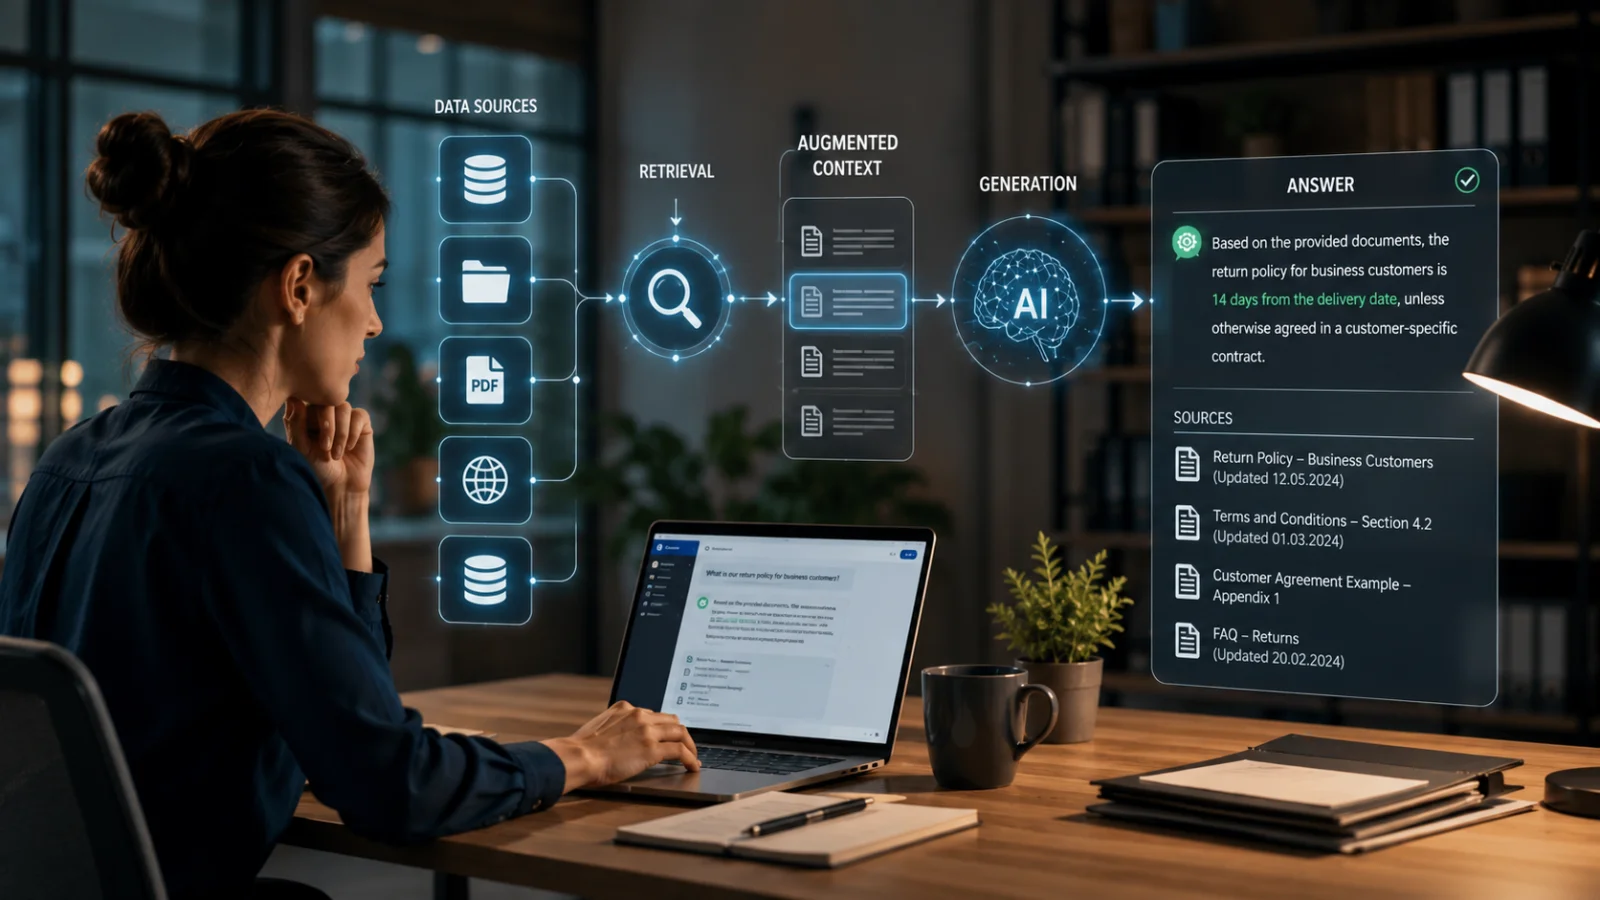
RAG stands for Retrieval-Augmented Generation. It is built on three ideas:
Retrieval — finding information
The system searches an external source for information related to the user's question. The source could be, for example:
- the company's internal knowledge base
- product documentation
- customer support guidelines
- the intranet
- contract templates
- research reports
- websites
- a database
- PDF documents
- a CRM or ERP system
- frequently asked questions
- training materials
Augmented — enriching the context
The retrieved information is added to the AI's context. In other words, the model receives the relevant material in addition to the user's question.
Generation — producing the answer
The language model builds an answer for the user based on the retrieved information.
Amazon Web Services defines RAG as a way to optimize the output of a large language model so that it references an authoritative knowledge base outside its training data. This helps the model produce more accurate and more useful answers.[2]
The key difference from an ordinary AI answer is this:
Without RAG, the model answers based on what it learned in training and what the user provides in the conversation. With RAG, the model also gets retrieved, more precise and often more current information for the specific question at hand.
3. Why was RAG developed?
RAG was developed to solve one of the fundamental problems of generative AI: language models are impressive, but their knowledge isn't automatically current, verified or specific to an organization.
A large language model may know a lot about the world in general. It can explain what cash flow is, how a SaaS business works or why customer retention matters. But it may not know:
- what your company's product guides actually say
- what the latest price list is
- what was decided in last week's board materials
- what today's customer support policy is
- what the organization's security policy allows
- how a particular contract version differs from the previous one
- what the current guidance from the authorities says
IBM Research describes RAG as an “open book” approach: the model isn't taking a closed-book exam but can use external sources to support its answer. According to IBM, the two main benefits of RAG are access to current, reliable facts and the ability for users to see which sources an answer is based on.[3]
This is a big change. A conventional language model is like a smart generalist who remembers a lot but can mix up the details. A RAG model is that same expert with the right documents laid out in front of them.
4. How does RAG work in practice?
A RAG system can be described in five steps.
1. The information is collected
First, material is brought into the system. It might include, for example:
- company documents
- website content
- guidelines
- knowledge base articles
- product descriptions
- customer support answers
- internal process descriptions
This step is often called data ingestion — bringing information into the system.
2. The information is split into pieces
Long documents are divided into smaller pieces, often called chunks. A chunk is a suitably sized piece of text, such as a few paragraphs or part of a page.
This matters because AI generally shouldn't read an entire document library for every question. It needs to find exactly the right passages.
3. The information is indexed
The document chunks are converted into a form that can be searched efficiently. This usually involves what are known as embeddings. An embedding is a numerical representation of text: the system turns text into a mathematical “fingerprint” that makes it possible to find similar content.
These are often stored in a vector database. This is a database designed to find content that is similar in meaning, not just content with the exact same words.
4. Relevant material is retrieved for the user's question
When the user asks something, the system searches the database for the related text chunks. If the question is:
“How does our company's return policy work for business customers?”
the RAG system might retrieve the return terms, the customer service guidelines and any relevant contract appendix.
5. The language model builds the answer from the sources
Finally, the language model receives the user's question and the retrieved text chunks. Its job is to build a clear answer based on them.
Google Cloud's description of the Vertex AI RAG Engine follows the same logic: data is brought into the system, transformed and chunked, indexed, retrieved in response to the user's question and passed to the model as context. Google emphasizes that additional context helps the model answer more accurately and reduces hallucinations.[4]
5. RAG explained with a simple analogy
Imagine two experts.
The first expert sits in a meeting room with no materials. They have read a lot and speak convincingly. When asked something, they answer from memory. The answer is often good. But if you ask about the latest price list, the exact wording of a contract clause or a decision made this week, they may get it wrong.
The second expert sits in the same room but has access to the company's documents, the latest guidelines and a search system. When asked something, they first look up the right passage and answer based on it.
That is the idea behind RAG. It doesn't make AI infallible. But it gives it a better desk to work from.
NVIDIA compares RAG to a court clerk: a large language model can be like a judge with a broad general understanding, but a specific case requires documents, precedents and sources. RAG acts as the “librarian” that fetches the material the model needs.[5]
The analogy is apt because it reveals the core of RAG: a good answer doesn't come from intelligence alone. It comes from the right information at the right moment.
6. How does RAG reduce hallucinations?
A hallucination is when AI produces information that sounds plausible but is wrong or made up. RAG reduces hallucinations because it anchors the answer in the retrieved material.
Without RAG, AI might answer like this:
“Your company's return period is 30 days.”
With RAG, the answer can be based on a document:
“According to the terms and conditions, the return period for business customers is 14 days, unless otherwise agreed in the customer-specific contract.”
The difference is huge. RAG helps in three ways in particular.
1. The model gets a factual foundation
When the model receives a relevant document, it doesn't have to invent an answer out of thin air.
2. The answer can be sourced
A good RAG system shows which document or passage the answer is based on.
3. The user can verify the claims
Sources make the answer more auditable. The user can open the original document and check whether the answer holds up.
Microsoft highlights reduced hallucinations and source transparency as key benefits of RAG. According to Microsoft, RAG can increase trust especially in high-stakes fields such as law, healthcare and finance, because users can check what the claims are based on.[6]
But an important caveat: RAG doesn't eliminate hallucinations entirely. It reduces the risk, provided the retrieval finds the right information and the model uses it correctly.
7. Why does RAG keep answers more up to date?
A large language model is trained on a particular dataset up to a particular point in time. Its internal knowledge can go out of date. RAG addresses this problem by connecting the model to external data sources that can be updated without retraining the entire model.
For companies, this is a huge advantage.
If the price list changes, you don't need to train a new language model — you update the price list document or the database. If the customer support guidelines change, you update the guidelines. If the law changes, you update the source material.
IBM highlights the benefits of RAG as access to current, domain-specific data and the ability of organizations to improve AI answers without costly model retraining.[7]
This is where the practical power of RAG shows. AI is no longer just a model that “knows what it knows.” It becomes an interface to a living knowledge base.
8. RAG in companies and organizations
In companies, RAG is one of the most important ways to make generative AI genuinely useful. Why? Because a company's value usually doesn't lie in general knowledge. It lies in its own data, its own processes, its own customers and its own documents.
RAG can help in use cases such as these:
Customer service
A chatbot can answer customer questions based on the company's own guidelines, terms and conditions and product information.
Sales
A salesperson can ask AI:
“What should I keep in mind about this customer before the meeting?”
RAG can retrieve CRM notes, previous quotes, support requests and customer segment data.
HR
An employee can ask:
“How does parental leave work at our company?”
RAG can retrieve the answer from HR guidelines and any local practices.
Legal and compliance
A lawyer or the compliance team can look up contract clauses, regulatory guidance and internal policies.
Product development
The product team can analyze customer feedback, support requests and roadmap documents.
Education
A new employee can ask about how the organization works and get answers based on onboarding materials.
Amazon Web Services describes RAG as a pragmatic and effective way to use language models in business, because it gives the model external data, such as a company's internal documents, that helps tailor its answers to a specific use case.[8]
Here is the business core of RAG: it turns AI from a general-purpose writer into an interface for the organization's knowledge work.
9. RAG in AI assistants: what should users understand?
The practical takeaway goes like this:
A RAG-based AI assistant retrieves current information to support its answers.
From the user's perspective, that is an important promise, but it is worth understanding correctly. RAG means the AI assistant can retrieve information from defined sources to support its answer before it responds. That way, the user doesn't just get a generic language model's guess but an answer based on the knowledge base available to the system.
In practice, this might mean, for example, that a RAG-based AI assistant:
- retrieves information from the organization's own documents
- uses up-to-date guidelines
- cites the source material
- reduces the risk of made-up answers
- can answer organization-specific questions
- helps the user find the right information faster
It is important to be honest, though: RAG doesn't automatically make any AI system perfect. In a RAG solution, the quality of the outcome depends on factors such as:
- how good the knowledge base is
- how up to date the sources are
- whether retrieval finds the right documents
- whether the model uses the retrieved information correctly
- whether sources are shown to the user
- how situations of uncertainty are handled
A good RAG system doesn't just answer. It helps the user see what the answer is based on.
That is why, when using a RAG-based AI assistant, it is worth asking:
“Show me which source this answer is based on.”
Or:
“If the answer isn't in the source material, say so directly.”
This makes using AI safer and more transparent.
10. The benefits of RAG: why is everyone talking about it?
RAG has quickly become one of the most important techniques in generative AI because it directly addresses AI's practical pain points.
10.1 Fewer hallucinations
When the answer is based on retrieved material, the model guesses less.
10.2 More up-to-date information
The knowledge base can be updated without retraining the model.
10.3 Organization-specific knowledge
RAG can draw on the company's own data, which a general language model doesn't know.
10.4 Better transparency
Source citations and document links help the user verify the answer.
10.5 Cost efficiency
RAG can be a lighter alternative to continuously fine-tuning or retraining a model.
10.6 Faster access to information
Users don't have to hunt down the right PDF, intranet page or guideline by hand.
10.7 Better customer experience
A customer service bot can give more accurate answers when it is grounded in the company's actual guidelines.
Google Cloud describes RAG as combining an organization's own data with the linguistic capabilities of language models, so answers can be more accurate, more up to date and more relevant to the user's needs.[1]
In this sense, RAG is a bit like a reality check for AI. It doesn't just produce text — it first finds the ground the text will be built on.
11. The limits of RAG: why isn't it a magic fix?
RAG is powerful, but it isn't magic. It can fail in many ways.
11.1 Retrieval can find the wrong information
If the system retrieves the wrong document or the wrong passage, the answer can go wrong. This is RAG's classic problem: the generation may be good, but the retrieval fails.
11.2 The information may be outdated
RAG keeps answers up to date only if the knowledge base is up to date. If the database contains an old guideline, AI may answer according to that old guideline.
11.3 Documents may contradict each other
If an organization has three different versions of the same guideline, RAG may retrieve the wrong one or mix them up.
11.4 The model may misinterpret the source
Even when the right document is found, the language model may misunderstand it or overgeneralize.
11.5 The source may not be enough to answer
If the retrieved context doesn't contain enough information, the model should say “I don't know.” Not every system does this well.
Google Research has highlighted the concept of sufficient context. The idea is that in RAG systems it isn't enough for the retrieved information to be relevant in some way. It has to be sufficient to answer the question correctly. If the context falls short, the model should recognize the uncertainty rather than make up an answer.[9]
This is an important insight. RAG isn't just a search engine plus AI. It is a question of quality: does the system find exactly the information needed for a correct answer?
11.6 RAG can create a false sense of security
When an answer includes source citations, it looks trustworthy. But a citation doesn't automatically mean the answer is correct. The source may be wrong, outdated or misinterpreted. That is why users still need to verify critical claims.
12. How do you build a good RAG system?
A good RAG system isn't created simply by connecting a language model to a folder of documents. It requires careful design.
12.1 A high-quality knowledge base
The first question is: what information goes into the system? If the knowledge base is messy, outdated or contradictory, the answers suffer too. A good knowledge base is:
- up to date
- curated
- clearly structured
- versioned
- maintained by designated owners
- access-controlled
12.2 Good document chunking
If documents are split into pieces that are too small, the context is lost. If the pieces are too large, retrieval can become imprecise. Chunking is a surprisingly important technical choice. It affects whether the system finds the right passage.
12.3 An effective retrieval method
Keyword search alone isn't always enough. Vector search finds content that is similar in meaning even when the words aren't exactly the same. The best solution is often hybrid search, which combines keyword search with semantic search.
12.4 Showing the sources
Users need to see what the answer is based on. A good RAG answer may include:
- the document name
- the section or page
- a link to the source
- a brief rationale
- a note of uncertainty if the source isn't sufficient
12.5 Clear instructions for the model
The model needs to be told how to behave. For example:
“Answer only based on the sources provided. If the sources don't contain the answer, say so directly.”
This reduces guesswork.
12.6 Evaluation and testing
A RAG system has to be tested with real questions. Amazon Web Services stresses the importance of evaluating the reliability of RAG applications: the system should be measured in terms of performance, reliability and potential bias, among other things.[10]
When testing, ask:
- Is the right source found?
- Is the answer based on the source?
- Does the model decline to answer when the information isn't there?
- Are the sources visible to the user?
- Is the answer too certain?
- Does the system work for different user groups?
Good RAG is an ongoing process, not a one-time project.
13. RAG vs. fine-tuning: when do you need which?
RAG is often confused with fine-tuning a model. They are different things.
RAG
RAG gives the model external information at the moment it answers. It is a good fit when:
- the information changes often
- you want to use the organization's documents
- sources need to be shown
- answers need to stay up to date
- you want to avoid retraining the model
Fine-tuning
Fine-tuning means further training a model on a specific dataset or for a specific task. It is a good fit when:
- you want to change the model's style
- you want to teach a specific answer format
- you want to improve performance on a narrowly defined task
- the data is relatively stable
- you need specific behavior, not just new knowledge
Often the best solution isn't either-or. A company can use RAG for current information and fine-tuning to teach, for example, a particular answer style or process.
But if the problem is “the model doesn't know our latest guidelines,” RAG is usually a more natural solution than fine-tuning.
14. The future: from RAG toward agents and intelligent knowledge work systems
RAG is already important, but its significance will grow as AI moves beyond simple chatbots toward agents.
An agent is an AI system that doesn't just answer a question but can carry out multiple steps: retrieve information, compare options, use tools, form a plan and perhaps even execute tasks.
RAG is core infrastructure for agents like these. If an agent is going to help an employee, it needs to know:
- what the organization's guidelines say
- what the customer has done before
- what is happening in the systems
- which rules must be followed
- which documents it is allowed to use
- what the information is based on
IBM describes the agentic RAG approach, in which a RAG system is combined with agent-like capabilities: the system can retrieve information from an external knowledge base and use it to produce more accurate, domain-specific answers without the model relying solely on its training data.[11]
In the future, users may not see RAG as a separate technique at all. They will see it as better answers.
The user asks, and the system:
- retrieves the right sources
- assesses whether they are sufficient
- builds an answer
- shows the sources
- states its uncertainty
- suggests the next step
This is a big step toward AI that doesn't just sound smart but works more reliably as part of everyday work.
15. Conclusions: what should you take away from this?
RAG is one of the most important techniques for bringing generative AI into real-world work. It solves three big problems:
- AI's knowledge can be outdated
- AI doesn't know the organization's own data
- AI can hallucinate convincingly
RAG doesn't make AI perfect. But it makes it more useful, more verifiable and better tied to real information.
These are the key takeaways:
1. RAG means AI retrieves information first and answers only after that
This is what sets it apart from an ordinary language model answer.
2. RAG reduces hallucinations but doesn't eliminate them entirely
Faulty retrieval, an outdated source or a poor interpretation can still lead to errors.
3. Sources are RAG's great strength
When an answer can be traced back to a document, the user can verify it.
4. Being up to date depends on the knowledge base
RAG is only as good as the data it uses.
5. In companies, RAG is the key to putting internal knowledge to use
It can turn an intranet, a document folder and a library of guidelines into a conversational interface.
6. When using a RAG-based AI assistant, ask it to show its sources
Users should ask: “What is this answer based on?”
7. The best RAG sometimes says: “I don't know”
A reliable system doesn't make up an answer when the sources aren't enough.
In the end, the core of RAG is simple: AI gets better when it doesn't have to answer alone.
When a model is backed by the right information, the right sources and the right context, it can help far more than a generic chatbot. It is no longer just a text machine. It is a researcher, an interpreter and a work partner — as long as people remember to keep asking, checking and using their own judgment.
16. Practical prompts for using a RAG system
Below are prompt templates you can use with any RAG-based AI solution.
16.1 Source-based answer
Answer only based on the available sources.
If the answer can't be found in the sources, say: “I can't find an answer to this in the available material.”
At the end of your answer, list the sources or documents it is based on.
16.2 Identifying uncertainty
Answer the question based on the sources. In your answer, distinguish between:
1) what the sources state with certainty
2) what can be inferred
3) what cannot be inferred from the material provided
16.3 Comparing documents
Compare these sources with each other.
Identify contradictions, overlaps and places where a newer document appears to supersede an older one.
Don't draw conclusions that the sources don't support.
16.4 Customer service reply
Write a clear reply to the customer based on the source material.
Keep the tone friendly and professional.
Don't promise anything that isn't stated in the sources.
If the matter requires a human to review it, say so clearly.
16.5 Decision support
Write a concise analysis of this topic based on the source material. Provide:
• the key facts
• potential risks
• open questions
• what should be checked before making a decisionDon't add outside information without labeling it separately.
16.6 Checking a RAG answer
Review your previous answer.
Tag each key claim with its source.
If a claim isn't based on a source, remove it or label it as an assumption.
The practical summary
If prompt engineering teaches you to ask AI better questions, RAG teaches AI to answer from better sources. That is the decisive difference.
Ordinary AI can sound right. RAG-based AI can show what its answer is based on. And that is exactly what makes it such an important technique for companies, experts and anyone who wants to use AI for more than brainstorming.
Practical tip: When you use a RAG-based AI assistant, ask it to show its sources and to tell you if the answer can't be found in the material. It is a small habit that builds greater trust in how you use AI.
Sources
- What is Retrieval-Augmented Generation (RAG)? — Google Cloud
- What is RAG? Retrieval-Augmented Generation AI — Amazon Web Services
- What is retrieval-augmented generation (RAG)? — IBM Research
- Vertex AI RAG Engine overview — Google Cloud Documentation
- What Is Retrieval-Augmented Generation aka RAG — NVIDIA Blog
- 5 key features and benefits of retrieval augmented generation — Microsoft
- O que é RAG (retrieval-augmented generation)? — IBM
- Understanding Retrieval Augmented Generation — AWS Prescriptive Guidance
- Deeper insights into retrieval augmented generation — Google Research
- Evaluate the reliability of RAG applications — AWS Machine Learning Blog
- What is Agentic RAG? — IBM